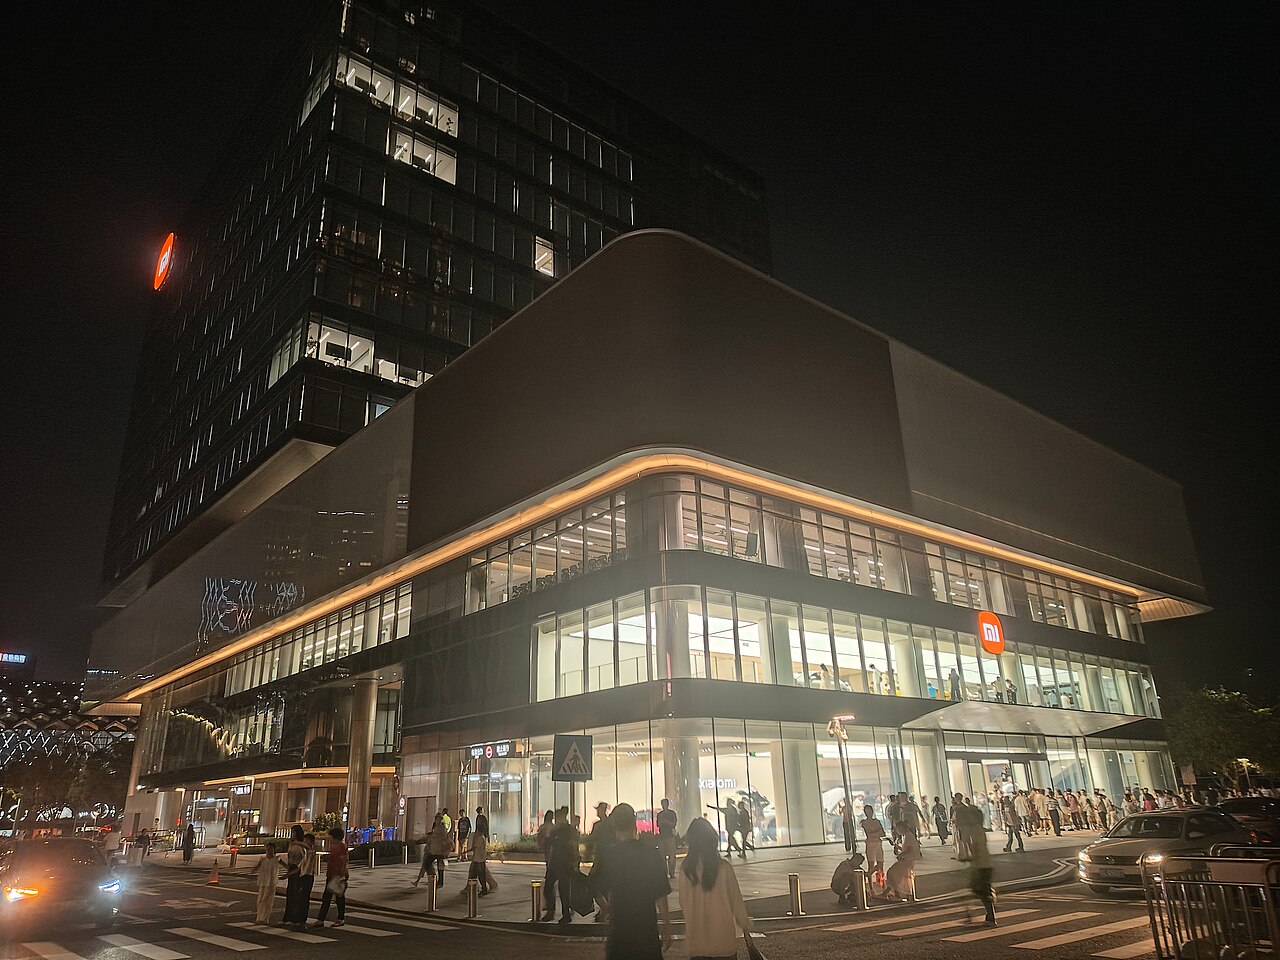
On September 22, 2026, Xiaomi, the company best known for smartphones, electric scooters and rice cookers, released and open-sourced the MiMo-V2.6 model series. The flagship, MiMo-V2.6-Pro, promptly topped Artificial Analysis's Intelligence Index among open-weight models with a score of 46, the highest any openly downloadable model has reached on that leaderboard and, by Artificial Analysis's own measurement, effectively level with xAI's closed Grok 4.7. A consumer hardware company now holds the best open-weight score in the world, and the release is worth reading carefully rather than taking at face value.
 MiMo
 Qwen
 DeepSeek
 Moonshot AI
 Z.ai
 Grok
The numbers behind the headline
MiMo-V2.6-Pro is a sparse mixture-of-experts model with roughly 1.02 trillion total parameters, of which about 42 billion activate on any given token. It takes a 1-million-token context window, is natively omnimodal (accepting text, image, video and audio), and ships under an MIT license, meaning the weights can be downloaded, modified and used commercially with essentially no restriction.
Artificial Analysis, the independent benchmarking firm, reports that evaluating MiMo-V2.6-Pro across its full evaluation suite cost $206.66, which works out to about $0.13 per Intelligence Index task, a fraction of what it costs to run the same suite against a closed frontier model. That figure describes the cost of the evaluation, not the model's own inference pricing, but it is a useful signpost for how the rest of this piece should be read: this is a model built to be cheap to test and, in the smaller variants, cheap to run.
An independent score, not a vendor's slide
Vendor benchmark tables are common in this market and worth reading skeptically, because the lab that built the model also chose which comparisons to show. That is not quite the situation here. Artificial Analysis is a third party that runs its own evaluation suite against every model it tracks, using the same methodology across vendors, so a score of 46 is not Xiaomi's own claim about itself, it is an outside measurement.
The top open-weight score, roughly level with Grok 4.7
Artificial Analysis Intelligence Index v4.3.2, an independent composite across reasoning, knowledge, math and coding evaluations. Higher is better. MiMo-V2.6-Pro leads every other open-weight model and sits 12 points behind the closed frontier leader.
Artificial Analysis Intelligence Index v4.3.2, September 22, 2026. Dark green marks MiMo-V2.6-Pro, lighter green marks other open-weight models, gray marks closed models. One index is one measure of capability, not the whole picture.
That independence matters, but it is not the whole story. The Intelligence Index is one composite built from a specific set of reasoning, knowledge, math and coding evaluations, weighted by Artificial Analysis's own methodology. A model can lead that particular index and still trail on tasks it does not test, or on evaluations weighted differently. MiMo-V2.6-Pro's own published results show exactly that kind of unevenness: strong marks on tasks like AutomationBench and Terminal-Bench 2.1, and a wider gap behind Claude Opus 5 on Terminal-Bench 4.0 and behind GPT models on some cybersecurity evaluations. A single leaderboard number is real evidence, not a verdict on every workload.
A model can lead one index and still trail on the tasks that index does not test. The score is evidence, not a verdict.
On reading a leaderboard win
Total parameters versus active parameters, and why it matters to whoever pays
The sparse mixture-of-experts design is the part of this release with the clearest practical consequence. MiMo-V2.6-Pro carries 1.02 trillion parameters in total but computes through only about 42 billion of them per token, a ratio of roughly 4 percent. That gap between total and active parameters is not a technical curiosity; it is the entire economic argument for building models this way. A large total parameter count lets the model store more knowledge and specialize different experts for different kinds of problems, while a small active count keeps the compute cost of generating each token far below what a dense model of the same total size would require.
One model family, three ways to pay for it
All three variants share a 1M-token context window and native text, image, video and audio input. The difference is total parameter footprint, the hardware needed to serve it, and price. Bar length is total parameters.
Pro-UltraSpeed is the same weights as Pro, priced roughly 10x higher for up to 20x the output speed. Serving Pro at all requires a multi-GPU cluster, which is the real cost of an open-weight release at this scale.
Xiaomi shipped that trade-off as three separate products rather than one. MiMo-V2.6-Pro is the full 1.02T/42B model for the hardest problems. MiMo-V2.6-Flash cuts the footprint to 309 billion total parameters with about 15 billion active, trading some capability for a model that fits on a single 8-GPU server rather than a multi-node cluster. MiMo-V2.6-Pro-UltraSpeed keeps the Pro checkpoint's capability but is served for latency, producing output Xiaomi says is up to 20 times faster, at roughly ten times the token price on OpenRouter's listing. None of that changes what the model knows; it changes what you are willing to pay to get an answer quickly versus cheaply.
Why a phone maker is doing this
MiMo is not a one-off side project. Xiaomi has been publishing models under the MiMo name since MiMo-7B in April 2025, followed by an open MiMo-V2-Flash in December 2025, a brief detour into proprietary-only V2-Pro and Omni models in March 2026, and a return to open weights with MiMo-V2.5 in April 2026, whose Pro variant scored 26 on the same Intelligence Index the current Pro now scores 46 on. Read against that history, MiMo-V2.6 is the fifth generation of a program that has been running for a year and a half, not a company parachuting into frontier AI for a press cycle.
The strategic logic is straightforward even if it is not stated outright: a company that ships hundreds of millions of phones, smart-home devices and, increasingly, electric vehicles has an obvious interest in the on-device and cloud AI features layered on top of that hardware, and controlling the underlying model removes a dependency on an outside vendor's pricing and roadmap. Xiaomi is also not doing this alone. It arrives amid a dense wave of Chinese labs, Alibaba's Qwen, DeepSeek, Moonshot's Kimi, Z.ai's GLM and others, releasing frontier-adjacent open-weight models on a near-monthly cadence, each one applying downward pressure on the price of running a capable model anywhere in the world.
What a leaderboard win does not prove
An open-weight release carries a form of verifiability a closed API cannot offer: once the weights are public, independent researchers can run the model themselves, reproduce or dispute the benchmark claims, probe it for safety issues, and fine-tune it without a rate limit standing in the way. That is a real advantage MiMo-V2.6 has over a closed model's self-reported numbers, MiMo-V2.6-Pro's score is checkable in a way a hypothetical closed equivalent's would not be.
It does not, however, settle questions about how a model was trained. On September 10, 2026, Anthropic published a threat intelligence report describing what it characterized as unauthorized, large-scale use of Claude by seven China-based labs, and named Xiaomi among them, alleging it routed roughly 400,000 requests through more than 1,500 accounts over a 20-day window in March and April 2026. Xiaomi has not publicly responded to that specific allegation, and the report does not draw a direct line from that activity to MiMo-V2.6-Pro's training data. The honest position is that a benchmark score tells you what a model can do on that benchmark; it tells you nothing about training provenance, and claims in either direction on that front deserve the same skepticism as any other unverified claim in this industry.
The serving-cost reality of an open trillion-parameter model
"Open weight" and "easy to run" are not the same thing. Xiaomi's own guidance puts MiMo-V2.6-Pro on a two-node cluster with 16-way tensor parallelism, hardware only a well-resourced team or cloud provider will have sitting around. Flash is the variant most teams could plausibly self-host, on a single 8-GPU node, and a smaller MiMo-V2.6-Distill-Qwen-9B checkpoint runs on one GPU for anyone who just wants a local model. For most builders, the practical choice is not whether to download 1.02 trillion parameters and provision a cluster; it is whether to call the hosted API, and increasingly, whether to keep that choice open. With a new frontier-adjacent, open-weight model arriving from a different lab every few weeks, each with its own price and its own strengths, treating the model as a fixed part of your stack is a bet that this month's leader stays the leader. Platforms like Metir that route each task to whichever model is currently strongest and cheapest for it exist for exactly this reason: a launch like MiMo-V2.6's is a reason to stay flexible, not a reason to commit.
The honest summary
Xiaomi's MiMo-V2.6-Pro is a real, independently measured, top-of-class open-weight result, backed by an MIT license and a genuine multi-generation research effort rather than a one-off stunt. It is also one score on one index, produced by a model that trails the closed frontier by roughly a dozen points and that, at its largest, requires serious infrastructure to actually run. Both of those things are true at once, and the release is most useful read as evidence in an ongoing competition rather than as a settled verdict on where open-weight models now stand.
Sources:
- Xiaomi's New Flagship Model Leads Open-Weight Rankings With a Score of 46 | Unite.AI
- Xiaomi MiMo V2.6: specs, benchmarks, and pricing explained | eesel AI
- Xiaomi MiMo-V2.6-Pro: 1.02T MoE, 1M Context and MIT-Licensed Weights | AiCybr
- Xiaomi MiMo-V2.6 Series: 3 New Models Officially Released | Xiaomi MiMo docs
- MiMo-V2.6-Pro - Intelligence, Performance & Price Analysis | Artificial Analysis
- Xiaomi MiMo-V2.6-Pro ties Grok 4.7 atop open-weights index | AI Weekly
- 'Better than DeepSeek': Xiaomi's MiMo-V2.6-Pro debuts as the top open weights model in the world alongside cheaper V2.6-Flash | VentureBeat
- [AINews] Xiaomi MiMo-V2.6-Pro 1T-A42B: the new top Open Weights model, trained for $3M | Latent Space
- Xiaomi MiMo | Wikipedia
- Anthropic Says Seven China-Based AI Labs Ran Industrial-Scale Claude Distillation Attacks | The Hacker News
- Anthropic disrupts Russian, Chinese AI campaigns targeting its Claude models | Rappler
Image credits
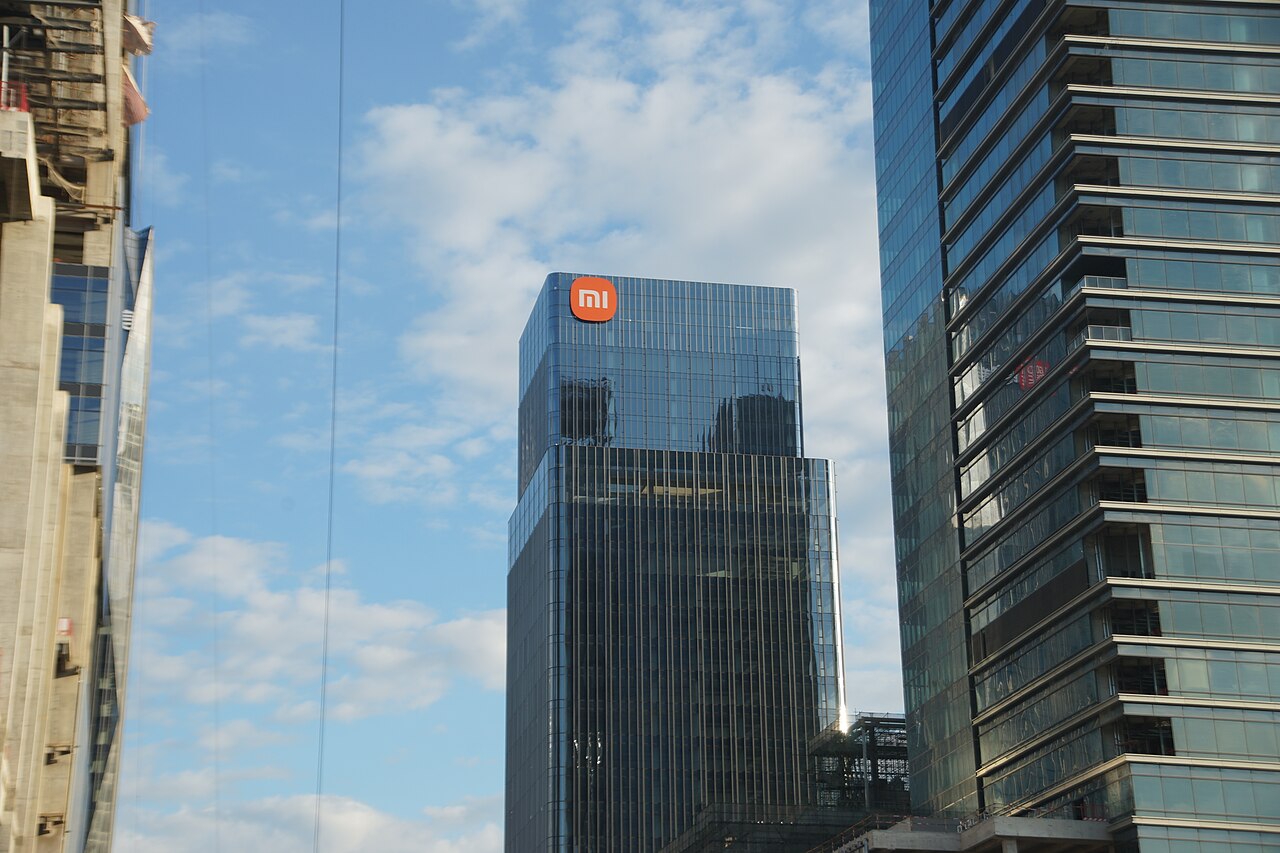
Hero image: Xiaomi Group's Shenzhen headquarters building at night, showing the illuminated Mi logo and ground-floor retail store, photographed by Lhzss8, via Wikimedia Commons, licensed under CC BY-SA 4.0. In-body photograph: Xiaomi's Guangzhou office tower, photographed by K.K.Serbia, via Wikimedia Commons, licensed under CC BY-SA 4.0. Both images show Xiaomi's corporate buildings and do not depict the MiMo-V2.6 model itself, which has no physical form to photograph.