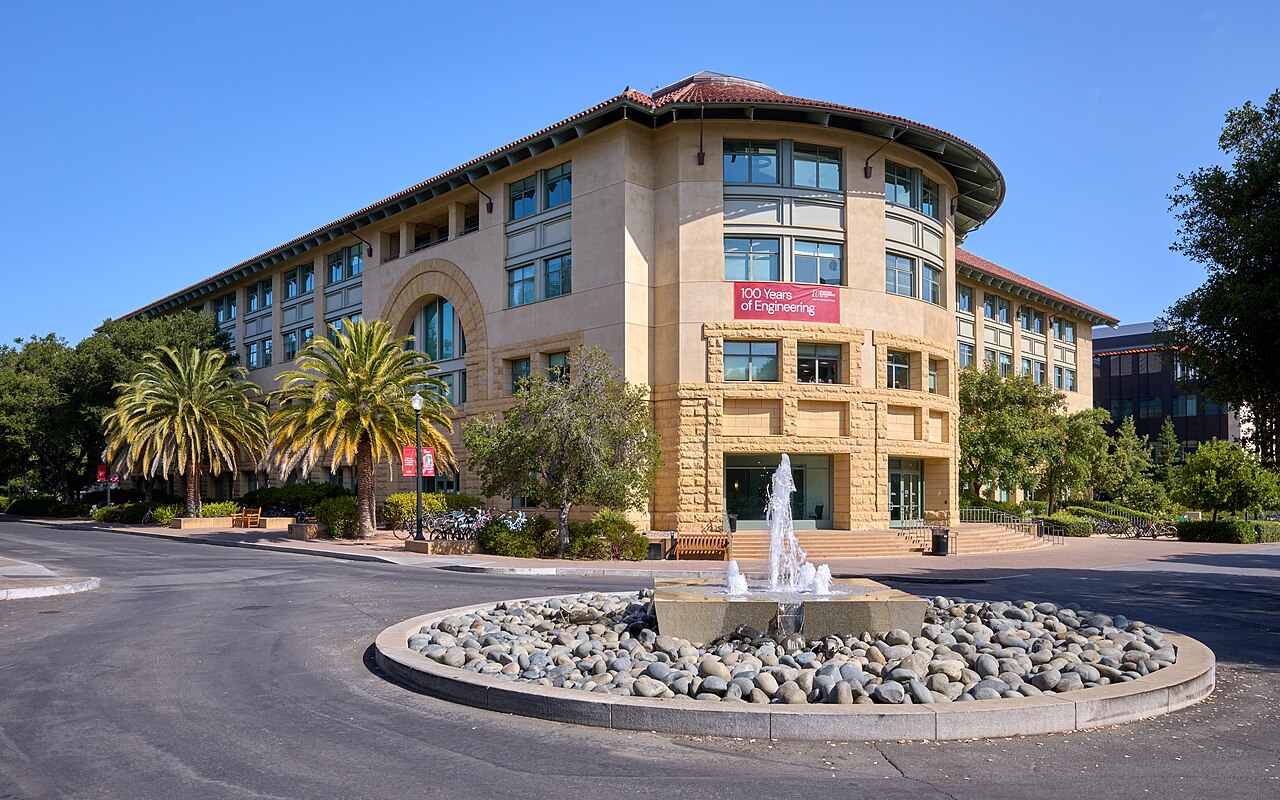
Snorkel AI raised $350 million in a Series E round announced September 22, 2026, valuing the seven-year-old startup at $3.5 billion. That is nearly triple the $1.3 billion valuation it carried after its $100 million Series D just 17 months earlier. The round was led by Insight Partners and S32, with participation from Third Point, March, Blumberg, Allegis, Standard VC and Frontline, alongside existing backers Addition, Lightspeed, Greylock, GV, P7, Wells Fargo, Walden Catalyst Ventures and Factory.
The headline number is the raise. The more interesting number sits underneath it: Snorkel's data-as-a-service offering, launched roughly a year earlier, grew more than 18x and crossed a $375 million annualized revenue run rate the week of the announcement. That growth rate, not the funding round by itself, is what the valuation is actually pricing.
Why expert training data became the bottleneck
For most of the last few years, the constraint on training a better language model was compute and, to a lesser extent, raw web-scale text. That constraint has shifted. Frontier labs have largely worked through the easily scraped internet, and the marginal gains from more of the same data have flattened. What moves a frontier model's performance now is different: reinforcement learning on carefully designed tasks, agentic environments that simulate real work, and evaluation sets built by people who actually understand the domain being tested, whether that is tax law, organic chemistry, or production-grade software engineering.
That kind of data cannot be scraped. It has to be built, by people with real subject-matter expertise, working alongside AI systems that can generate candidates, check consistency and flag edge cases. Snorkel's own founder and CEO, Alex Ratner, has put it directly: labs increasingly need "harder, higher-stakes data" to train and evaluate systems that have already absorbed most of the easy material, and that data is "becoming more rare, more specialized, more difficult to find." That scarcity, more than any single company's growth story, is the economic condition this round is pricing.
Data is becoming more rare, more specialized, more difficult to find.
Alex Ratner, Snorkel AI co-founder and CEO
From Stanford research project to data supplier
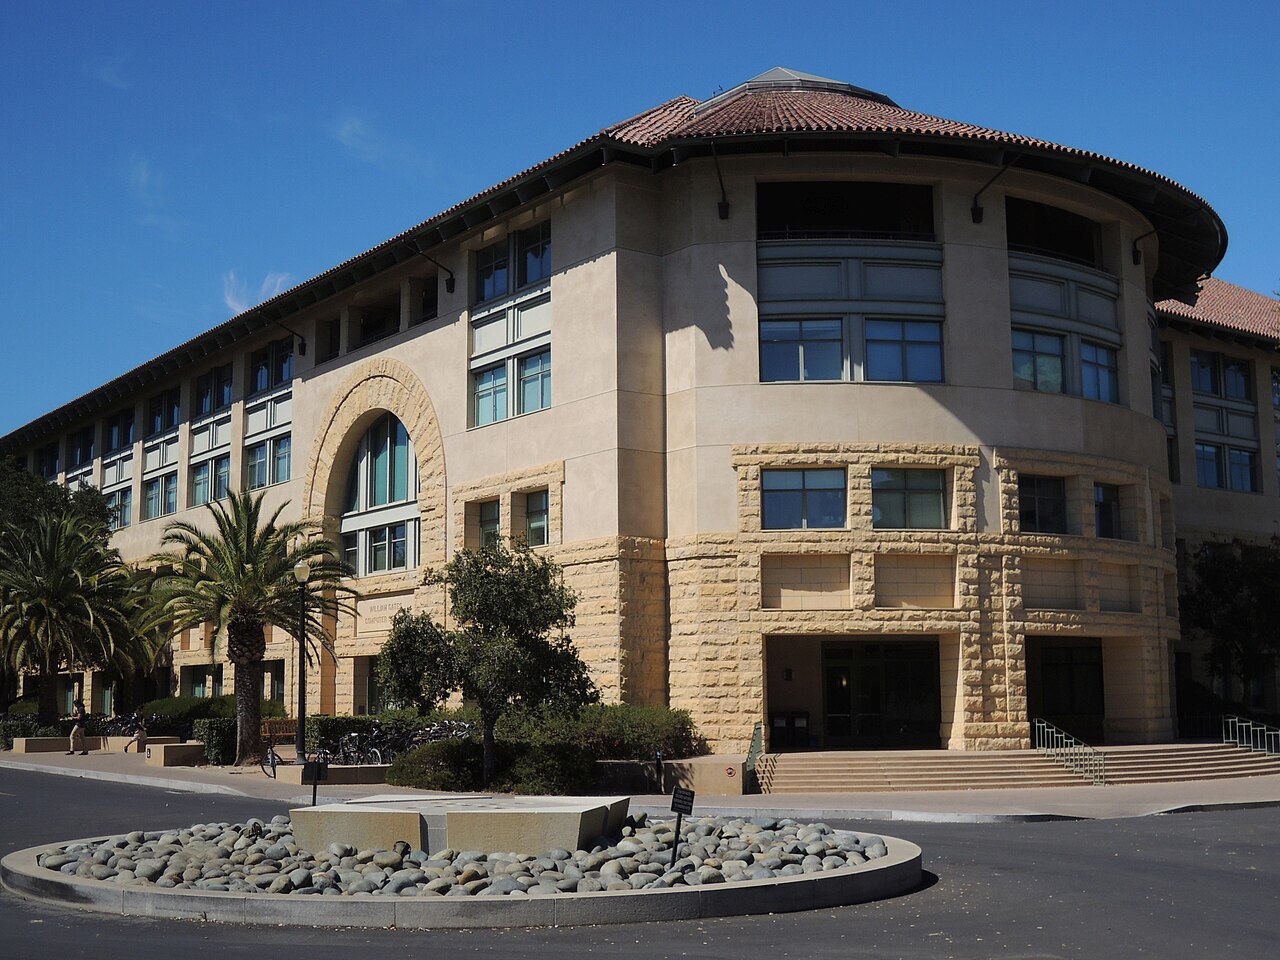
Snorkel's origin matters to how it is positioned today. The company began as a research project inside the Stanford AI Lab, built around "data programming," a technique for using weak, programmatic supervision rather than purely hand-labeled examples to train models faster and cheaper. That academic lineage, now seven years and roughly $237 million of prior funding removed from its founding, put Snorkel inside the labeling and data-quality problem years before "training data" became a headline venture category.
The pivot: selling the dataset, not the tool
For most of its history, Snorkel sold software: tools that let a customer's own team label and manage training data more efficiently. That is a real business, but it is bounded by how many seats a customer buys. Roughly a year before this round, Snorkel launched a different model, delivering finished, expert-graded datasets and reinforcement-learning environments directly, rather than the tools to build them in-house.
Selling the dataset, not the tool
The pivot behind the run-rate growth: Snorkel stopped licensing labeling software and started delivering the finished, expert-graded data itself.
Selling completed data lets revenue scale with the volume and difficulty of data delivered, rather than with the number of software seats a customer buys.
The economics of that shift explain the growth rate better than anything else in the story. A software license caps revenue at what a customer is willing to pay per seat. A finished dataset does not have that ceiling: the price scales with the volume, difficulty and specificity of the data delivered, and a single frontier-lab contract for a hard evaluation suite can be worth far more than a year of software licenses to the same customer. Snorkel describes the underlying operation as an "agentic data development platform," pairing tens of thousands of human specialists with its own narrower AI models and agents to produce and verify the data at a pace no manual-only process could sustain. Coding tasks reportedly make up the largest share of current demand, alongside domain-specific reasoning and agentic-environment work.
A valuation that nearly tripled in 17 months
Snorkel AI's two most recent rounds, sized by post-money valuation. The bar length is the valuation; the badge is the amount raised in that round.
The valuation jump tracks a business-model shift, not just investor enthusiasm: Snorkel's data-as-a-service revenue run rate grew roughly 18x over the same period.
| Series D | Series E | |
|---|---|---|
| Announced | May 2025 | September 22, 2026 |
| Raised | $100M | $350M |
| Valuation | $1.3B | $3.5B |
| Lead investor(s) | Addition | Insight Partners, S32 |
| Business model | Data-labeling software | Data-as-a-service |
| Annualized revenue run rate | Reported around $20M | $375M |
Who is buying, and the 2026 data-economy context
Snorkel says it now works with "frontier labs, hyperscalers, neolabs, vertical AI leaders, enterprises, and U.S. government agencies," a customer list broad enough that it functions as a proxy for who is currently spending heavily on model quality rather than just model scale. That breadth is also why investors are willing to price training-data suppliers as infrastructure rather than as a services business: a services company's revenue tracks headcount, but a data-as-a-service business's revenue tracks how much the entire industry is willing to spend on getting model behavior right.
This round arrives inside a broader repricing of the category. Meta's roughly $14.3 billion investment in rival data supplier Scale AI in June 2025 was widely read as training-data companies moving from vendor status to strategic infrastructure in investors' eyes, and it set a reference point every subsequent data-supplier round gets measured against. Snorkel is not alone in riding that wave; reporting on the round names Mercor, Handshake, Micro1 and Surge AI as other data suppliers posting comparably steep revenue growth over the same period, several of which reportedly pass 60 to 70 percent of gross revenue through to the domain specialists doing the work. That detail matters for how durable the margins in this category actually are: a business built on paying experts a large majority of revenue looks structurally different from a pure software margin, even at a $3.5 billion valuation.
 Meta
What "the frontier lab for AI data" actually claims, and what it does not settle
Ratner has described Snorkel's ambition as building something like a frontier lab, not for models, but for data itself: a system that uses AI agents to help produce, check and improve the next generation of training data, in a loop that in principle compounds the way frontier model training itself does. It is a genuinely different framing from "we label your data faster," and the run-rate growth suggests customers are, at minimum, paying for the difference.
What it does not settle is whether that advantage is durable. The skill this business depends on, recruiting and coordinating large pools of verified domain experts and pairing them efficiently with AI tooling, is not obviously proprietary in the way a model architecture or a training run can be. Several well-capitalized competitors are building toward the same position at the same time, and a customer base concentrated among a handful of frontier labs means the revenue is exposed to how many labs are simultaneously in an active scaling phase, and to whether those labs eventually choose to build equivalent expert-data operations in-house rather than buy them. The honest read is that Snorkel has clearly found a fast-growing, well-priced niche in the current AI training pipeline; whether that niche stays a moat or becomes a commodity that several suppliers compete away is not something a single funding round can answer.
For teams building on top of these models rather than training them, the practical takeaway is a step removed but still real: the quality gap between models is increasingly a function of what each lab paid for the training and evaluation data behind it, not just the compute spent on the run. That is part of why relying on any single model vendor is a narrower bet than it looks. Platforms like Metir AI give teams access to models from multiple labs side by side, so a quality edge that comes from one lab's data pipeline this quarter does not lock a workflow into that lab indefinitely.
Sources:
- Snorkel AI triples valuation to $3.5B as demand for AI training data booms | TechCrunch
- Snorkel AI raises $350M Series E at $3.5B valuation to build "the frontier lab for AI data" | unite.ai
- Exclusive: Snorkel AI valued at $3.5 billion amid surging demand for complex AI training data | Investing.com
- Snorkel AI raises $350M, completes pivot to data service | Runtime
Image credits
Header image: exterior view of the Gates Computer Science Building on the Stanford University campus, photographed June 16, 2025, by King of Hearts via Wikimedia Commons, licensed under CC BY-SA 4.0. In-body photograph, a different angle of the same building showing its Computer Science signage, by Jawed Karim via Wikimedia Commons, licensed under CC BY-SA 4.0. Neither photo depicts Snorkel AI's own offices or product; both show Stanford University's real Gates Computer Science building, home to the Stanford AI Lab where Snorkel's underlying research originated.